Structure the Task, Then Let RL Improve It
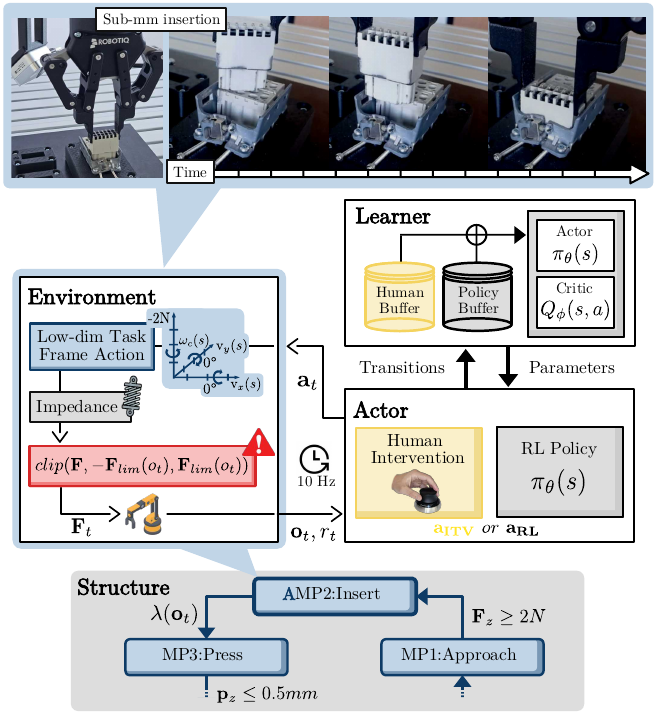
- We combine priors readily available in industry with sample-efficient off-policy RL, and show that the two are synergistic.
- As such, SHaRe-RL serves as a bridge between recent advances in RL and well established robotics formalisms for task frames, manipulation primitives, and compliant control.
- This enables domain experts to guide online learning without robot learning expertise.
Main Results
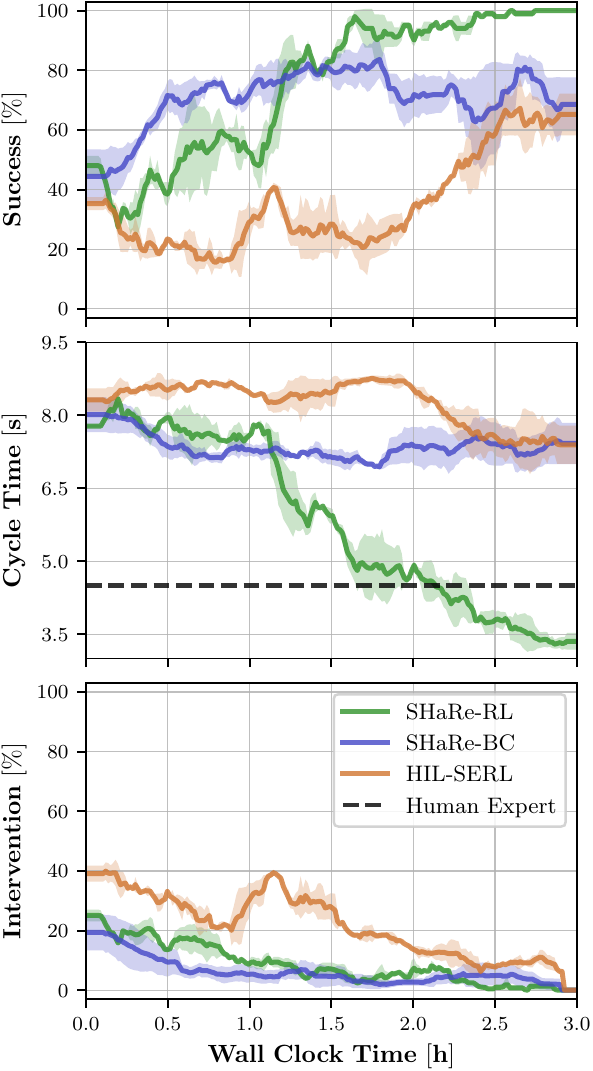
On a challenging tight tolerance insertion task, structure changes what online RL can learn within a practical wall-clock budget.
- SHaRe-RL reaches robust insertion performance in under three hours of real-world interaction.
- The unstructured HIL-SERL baseline does not reach the same level of performance within the considered time budget.
- Behavioral cloning is bounded by the suboptimality of the demonstrator, while RL improves through its own experience and eventually surpasses the demonstrator cycle time.
- We ensure safety during exploration through a simple mechanism that bounds contact forces while preserving free-space dynamics.
Zero-Shot Generalization
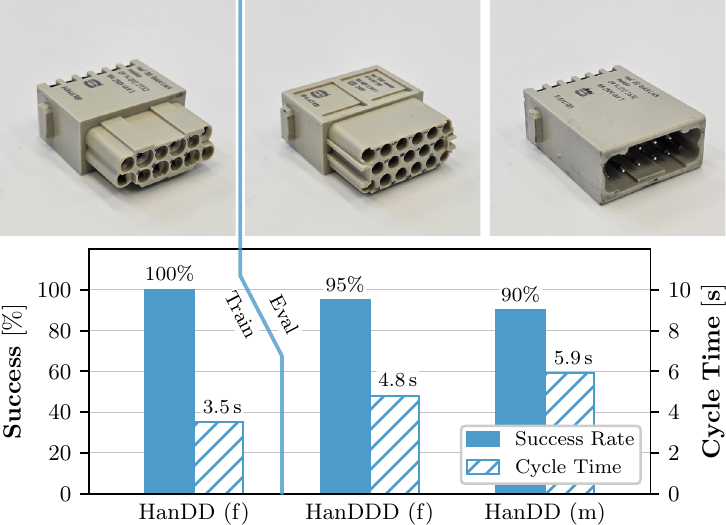
The learned policy transfers to previously unseen connector variants without additional environment interaction.
This zero-shot behavior suggests that the structured task representation captures reusable assembly knowledge instead of overfitting to a single part geometry.
BibTeX
@misc{stranghoener2025sharerl,
  title = {SHaRe-RL: Structured, Interactive Reinforcement Learning for Contact-Rich Industrial Assembly Tasks},
  author = {Strangh{\"o}ner, Jannick and Hartmann, Philipp and Weigelt, Lisa-Marie and Braun, Marco and Wrede, Sebastian and Neumann, Klaus},
  year = {2025},
  eprint = {2509.13949},
  archivePrefix = {arXiv},
  primaryClass = {cs.RO},
  doi = {10.48550/arXiv.2509.13949},
  url = {https://arxiv.org/abs/2509.13949},
  note = {Accepted to IEEE International Conference on Robotics and Automation (ICRA) 2026}
}